Evals
Test cases plus objective criteria, run after every change. Without evals, every prompt tweak is guesswork.
In one sentence
The set of test cases and objective criteria that measures the quality of the AI system, run automatically after every change.
Before
Change to the prompt, tool, or model
What it does
Runs cases + objective criteria
After
Approves the deploy, or blocks it
Analogy
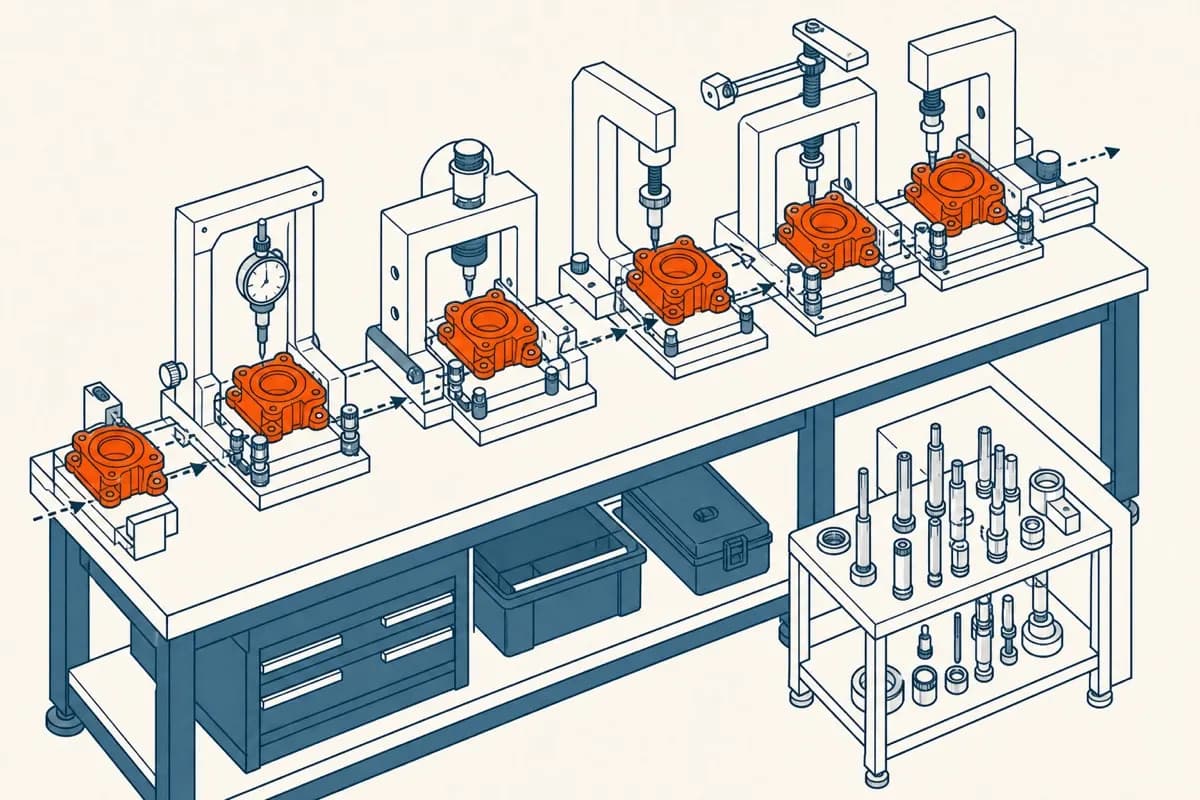
Think of quality control on a production line. No one asks "do I think this turned out well?" part by part; there is an answer key and a test that always runs the same way.
Example
The suite runs the 200 letters from the golden dataset and measures five criteria:
- Factual fidelity: every claim has a source in the field report (automatic verification)
- LGPD: no prohibited data, such as address, school name, or the child’s last name
- Language: the sponsor’s, which may be different from the report’s language
- Length: between 180 and 320 words
- Tone and dignity: evaluated by LLM-as-Judge
Each prompt change triggers the full suite, which takes 6 minutes and costs R$ 4, less than a meeting to debate whether it turned out well.
The common mistake
Thinking that "we tested it with about 10 examples and it looked great" is an eval. That is an impression. An eval must be reproducible, versioned, and run in full after every change.
The second mistake is subtler: measuring only what is easy to measure. Word count goes into the suite, while tone and fidelity are judged by eye, and the system improves precisely on what matters least. Subjective criteria also go into the suite, evaluated by LLM-as-Judge.
In practice
- Start with 20 cases and 3 criteria. A suite with 200 cases and 12 criteria tends not to get run, and then it measures nothing.
- One script, one command, output as a table with percentage by criterion.
- Version the suite together with the prompt: they change together.
- A suite failure blocks the deploy, like a software test.
- Typical tools: Promptfoo, Langfuse, or 100 lines of Python. The habit of running it matters far more than the choice of tool.
How to make it tangible
A script that runs the answer key cases against the criteria and prints the percentage for each one.
Note
Satisfaction (% achievement) is the informal version of this: how much the delivered result met the desired outcome. It works at the beginning, but any satisfaction criterion that repeats twice should become an item in the suite. Otherwise, the evaluation still depends on who was in the room.
Connects with
Translated from Portuguese with AI assistance.